Food for thought: ISOMICRO profile of Web Prolog

Hi,

I miss an ISOMICRO profile of Web Prolog, a profile
that can run on small embedded devices, and only
single threaded. Like Python can do for example.

I deleted my previous post, since it drifted into
high performance computing. It was a reaction of
mine, to these results and how they were viewed.

But the results have a few drawbacks. They use a highly
specialized π-WAM Prolog subset and a highly specialized
Hack VM backend. Also the ping pong code was optimized.

So I guess this high performance view is too specific
for the actor model. So to get a more general comparison,
I tried something else. I used a Python implemented Prolog

and a Python asyncio.Future implemented one element
channels, the later equals SWI-Prolog queues with max_size=1.
Finally I used the classical ping pong. Now with PyPy as the Python

runtime the results are, 6x times faster than the shared database
on a SWI-Prolog server provided by Torbjörn Lager. Difficult
to judge maybe my machine is just 6x times faster? One could

install PyPy, download Dogelog Player and run it on the server:

?- between(1,3,_), time(ping_pong(100000)), fail; true.
% Time 812.000 ms, User 54 %, Lips 5977 k
% Time 703.000 ms, User 53 %, Lips 6915 k
% Time 766.000 ms, User 64 %, Lips 5339 k
true.

But this makes me ask, where would one see using for
example SWI-Prolog Engines for the actor model, so that it
becomes competitive to asyncio.Future? Any idea how to do it?

I guess asyncio.Future only uses a micro queue or something.
This would give the ISOMICRO profile of Web Prolog, a profile
that can run on small embedded devices single threaded.

The opposite of high performance computing (HPC).

Bye

P.S.: Here the source code, first what was used for validation:

classic ping pong with channels and with logging
:- ensure_loaded(library(util/tasks)).

% ping(+Integer, +Object, +Object)
ping(0, P, _) :-
   send(P, finished),
   write('Ping finished'), nl.
ping(N, P, Q) :- N > 0,
   send(P, ping(Q)),
   recv(Q, pong),
   write('Ping received pong'), nl,
   M is N-1,
   ping(M, P, Q).

% pong(+Object)
pong(P) :-
   recv(P, M),
   (M = finished,
       write('Pong finished'), nl;
    M = ping(Q),
       write('Pong received ping'), nl,
       send(Q, pong),
       pong(P)).

% pong(+Integer)
ping_pong(N) :-
   chan(P),
   chan(Q),
   create_task(ping(N,P,Q),S),
   create_task(pong(P),T),
   task_join(S),
   task_join(T).
And the validation output:

log of running N=3

?- ping_pong(3).
Pong received ping
Ping received pong
Pong received ping
Ping received pong
Pong received ping
Ping received pong
Ping finished
Pong finished
true.

And what was used for benchmarking:

classic ping pong with channels and without logging
:- ensure_loaded(library(util/tasks)).

% ping(+Integer, +Object, +Object)
ping(0, P, _) :-
   send(P, finished).
ping(N, P, Q) :- N > 0,
   send(P, ping(Q)),
   recv(Q, pong),
   M is N-1,
   ping(M, P, Q).

% pong(+Object)
pong(P) :-
   recv(P, M),
   (M = finished;
    M = ping(Q),
       send(Q, pong),
       pong(P)).

% pong(+Integer)
ping_pong(N) :-
   chan(P),
   chan(Q),
   create_task(ping(N,P,Q),S),
   create_task(pong(P),T),
   task_join(S),
   task_join(T).

Thanks for the suggestion. I think it raises two distinct questions:

  1. Should Web Prolog define another interoperability profile below RELATION?
  2. Could the ACTOR profile be implemented using engines rather than one SWI-Prolog thread per actor?

My answers are: probably not to the first, and certainly yes to the second.

The Web Prolog profiles describe externally observable language and interaction capabilities, not implementation strategies. A node is RELATION, ISOBASE, ISOTOPE or ACTOR according to the semantics and APIs it exposes. Whether those semantics are implemented using operating-system threads, engines, coroutines, event loops, Web Workers or something else is deliberately left open.

A small, single-threaded implementation could therefore implement RELATION, ISOBASE or ISOTOPE. If it provided the complete actor semantics, it could even implement ACTOR. “ISOMICRO” might be a useful description of an implementation class or deployment target, but I do not think it belongs in the semantic profile hierarchy.

This distinction is important to the larger purpose of Web Prolog. The most ambitious part of the project is not a particular scheduler or actor implementation, but the proposal that Web Prolog could become a lingua franca through which otherwise incompatible Prolog systems communicate. An engine-based node would be entirely welcome, but it need not define a new profile merely because it uses a different execution substrate.

Engines are not an unexplored alternative here. In an earlier version of SWI Web Prolog, Jan Wielemaker kindly helped me build an engine-based actor implementation:

That implementation used an M:N arrangement: actor engines were scheduled over a smaller pool of worker threads. Messages were placed on a dispatch queue, workers resumed engines using engine_post/3, and an actor waiting in receiveyielded until it was scheduled again. The implementation also dealt with timeouts, termination and expansion of the worker pool.

That is a perfectly legitimate architecture and may be attractive when very large numbers of mostly dormant actors are required. It does not, however, make the scheduling problem disappear. Scheduling, mailbox wakeups, fairness, timeout handling, cancellation and worker-pool management become responsibilities of the Web Prolog runtime rather than the underlying Prolog system.

I must also confess that I never became sufficiently comfortable with the scheduler to maintain and extend it with confidence. The current one-actor-per-thread implementation is conceptually much simpler and maps more directly onto both the actor model presented in the book and SWI-Prolog’s existing concurrency primitives. I do not recall the engine version being faster, and I would not expect engines to be inherently faster in every workload. They can reduce some resource and scheduling costs while introducing others.

The reasonable efficiency of native local Web Prolog actors is largely inherited from Jan Wielemaker’s implementation of the SWI-Prolog thread_* and message-queue predicates. In the current implementation:

  • spawn/2-3 ultimately creates an SWI-Prolog thread;
  • message sending ultimately uses thread_send_message/2;
  • receiving ultimately uses thread_get_message/1-3.

For sustained local computation, an actor therefore runs in the same Prolog VM and on the same SWI-Prolog thread machinery as code started directly with thread_create/3. The Web Prolog layer adds bookkeeping and semantics – actor identifiers, private modules, initialisation, links, monitors and selective receive – but it does not introduce another interpreter or scheduler.

Actor creation is consequently not identical in cost to a bare thread_create/3, and the comparison changes substantially when src_* installation, browser actors or communication between remote nodes is involved. Those facilities are part of the larger system rather than costs inherent in local message passing.

The current implementation can be inspected here:

After more than 400 pages and a demonstrator covering actors, nodes, remote spawning, toplevels, supervision, statecharts, HTTP APIs and browser integration, I am unlikely to redesign the project around engines without a compelling architectural reason. Page count is not evidence that the design is correct, of course, but it does mean that an alternative must be judged against the complete architecture, not only a small ping-pong benchmark.

My next step is therefore to concentrate on making the SWI-Prolog node production-ready. I nevertheless welcome competing implementations, including engine-based or single-threaded ones. If they implement the same profiles and can communicate with other Web Prolog nodes, that would support the larger goal of reducing Prolog fragmentation – and would be more significant than which implementation wins a particular microbenchmark.

As a concrete illustration of the distinction between interoperability profiles and implementation techniques, I have also made a small proof-of-concept implementation in Ciao Prolog:

It implements the client-facing stateless /call API associated with the RELATION and ISOBASE profiles. A client supplies a goal and answer template and can retrieve the solutions in pages. Queries are evaluated against a pure, node-resident Ciao module.

Interestingly in the context of this discussion, the Ciao implementation uses engines internally for answer generation and continuation caching. That choice is invisible to the client: the external protocol remains the same.

This is not yet a complete or production-ready Web Prolog node. It is a proof of concept showing the intended direction: different Prolog systems should be able to implement the same Web Prolog APIs using whatever execution mechanisms suit them. They can then interoperate without having to share an implementation, scheduler or even the same underlying Prolog system.

In that sense, engines and threads are not competing additions to the profile hierarchy. They are alternative ways of implementing the capabilities described by a profile.

By Occams Razor, it wouldn’t be about the profile levels up and
down. Because ping pong only needs a very small subset of
the actor model (and π-calculus likewise). Only the following things

(could say intra node) are used for ping pong and for its steady state:

  • send
  • recv
  • process/channel mobility (one message is ping(_))
  • What else?

Because we would assume the harness that starts the ping
pong example doesn’t count. So when the ping pong example
is on one of your shared database, we ignore for the moment

how it gets there and how it gets started. Same for my take
in Dogelog Player which has a totally different invocation
with create_task/1 and task_join/1.

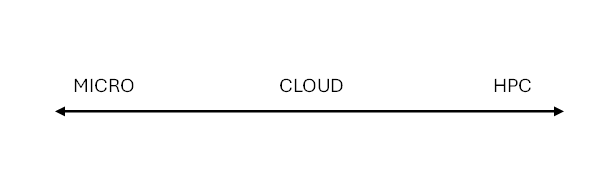
Now the question is are there some dimensions that dont
go down and up your levels. But that go left and right
along this spectrum, namely:

I take my example running single threaded (in fact also auto-yield)
as an instance of ISOMICRO, and lets say yours is ISOCLOUD
remotely execute somewhere in a cloude node, and then

maybe we have other things like ISOHPC, etc.. etc..
What makes them run alike? An “ether”. Well an “ether”
in the sense how to reach the “cloud” node is not in

the scope, we do not consider that. Mostlikely there are
some possibly variations in specifications. Like
ISOCLOUD has preemptive scheduling und unbound

queues, we might have examples ping1, ping2, etc.. that
show phaeomene that happen or don’t happen with premptive
scheduling or unbounded queues, and we could then

prepare a criteria catalogue with “yes” and “no” for these
dimensions. And have a handle on these dimensions, the
elephant in the room getting more shape than bits and pieces.

I think this reformulation brings us closer together. A MICRO — CLOUD — HPC dimension would be orthogonal to the cumulative hierarchy

RELATION ⊂ ISOBASE ⊂ ISOTOPE ⊂ ACTOR

rather than adding another level below RELATION.

I should add that Chapter 3 already contains a subsection entitled “Could there be other profiles?” There I explicitly say that the proposed hierarchy is not intended to be a closed taxonomy. I also consider cross-cutting profiles that express restrictions, guarantees or disciplines concerning how a node provides its capabilities. PURE is given as one possible example.

I am therefore not rejecting additional profiles in principle. The question is what turns an implementation description into an interoperability profile. In my view, it must define a sufficiently precise and externally observable contract against which implementations can be tested.

“Micro,” “cloud” and “HPC” do not yet provide such contracts. They primarily describe deployment targets. A cloud implementation need not use preemptive scheduling or unbounded mailboxes, while a micro implementation need not use cooperative scheduling or bounded ones.

Your proposed criteria catalogue could nevertheless be a useful first step. It might record dimensions such as:

  • cooperative versus preemptive scheduling;
  • bounded versus unbounded mailboxes;
  • local versus distributed addressing;
  • message-ordering guarantees;
  • isolation and failure semantics;
  • support for process, actor or channel mobility.

Properties that affect portable client behaviour might eventually justify optional, cross-cutting profiles. Purely internal implementation choices would remain implementation metadata.

There is also an important consequence of excluding the harness from the ping-pong comparison. Once actor creation, source installation, database population, isolation, routing and remote communication are ignored, the steady state measures only local send and receive. That is a legitimate microbenchmark, but it cannot by itself classify the surrounding system as micro, cloud-oriented or distributed.

Similarly, ping(_) does not by itself demonstrate process or channel mobility. Mobility normally requires a process, actor or channel reference to be transmitted and subsequently used by the receiver to alter the communication topology.

The “ether” connecting heterogeneous systems is precisely where the Web Prolog profiles matter: common term representations, addressing and HTTP or WebSocket protocols. If communication and reachability between nodes are set aside, we are comparing local runtime mechanisms rather than interoperability.

So yes, I welcome the criteria catalogue, and Chapter 3 already leaves conceptual room for profiles beyond the four I propose. I would simply reserve the word profile for a specified and testable contract, rather than applying it immediately to broad deployment categories.

You are right about one general point: a stateless protocol can carry operations that have effects. Stateless means that each request contains the information needed to interpret it; it does not mean side-effect-free. I do not claim otherwise.

That is not, however, what distinguishes the four Web Prolog profiles. They are not four philosophical degrees of purity:

  • RELATION exposes selected owner-defined relations and need not contain a Prolog engine at all.
  • ISOBASE exposes a portable Prolog language basis through the stateless HTTP API.
  • ISOTOPE adds facilities such as private database updates, I/O and operators, together with the semi-stateful toplevel API.
  • ACTOR adds asynchronous messaging, actor lifecycle, supervision and the stateful WebSocket API.

ISOBASE is not a PURE profile. Indeed, Chapter 3 discusses PURE separately as a possible cross-cutting profile.

I am of course aware of ISO/IEC 13211-1; it is one of the foundations on which the profile hierarchy is built. But the ISO core standard does not specify HTTP endpoints, remote answer streams, term and error encodings, paging, source installation, toplevel sessions, actor addressing or cross-node communication. Referring to the ISO standard therefore cannot replace the Web Prolog contracts.

There is also a practical reason for separating /call from the more capable APIs. /call is a GET interface. HTTP defines GET as a safe method: the client should not be requesting a change to the origin server’s state. This matters because GET requests can be cached, retried, prefetched and followed automatically. RFC 9110 explicitly warns against placing unsafe actions in GET query parameters.

The fact that a server may log a GET request, update an internal cache or perform other incidental effects does not change the requested semantics. By contrast, the semi-stateful API uses POST operations and gives the client a persistent toplevel computation. That is where database updates, continuing answer production, input, output and interruption belong. The WebSocket API then adds asynchronous actor communication.

Collapsing this into “ISO core” and “TRINITY web” would discard useful distinctions. A simple database wrapper can implement RELATION without implementing Prolog. A Prolog system can implement ISOBASE without mutable sessions or actors. Another can implement ISOTOPE without implementing distributed message passing. These are meaningful differences for implementers, clients, security policy and conformance testing.

All of this is described in Chapter 3. I do not expect you to agree with the design, but before I answer further proposals to replace it, could I ask you to read that chapter and the sections explaining the three APIs? Otherwise I will simply be reproducing the book piecemeal in forum replies.

After that, I will be happy to discuss specific disagreements with what the architecture actually proposes.

Thank you for clarifying that ISOMICRO is a separate project and a philosophical as well as an implementation fork of Web Prolog. In that case, there is no need for us to reach agreement about the Trinity’s profile structure. You are of course welcome to explore your alternative, and I welcome the competition.

I have explained the rationale for the Trinity’s profiles and three APIs, and the book and demonstrator provide the fuller account. I do not think another point-by-point exchange would be productive, so I will leave the discussion here. Good luck with ISOMICRO.

Hi,

The scales ISOCLOUD, ISOHPC, are further projects.

Bye