BIG DISCLAIMER: This is a rant, don’t take it too seriously.
tldr: Just add prefix to predicates from same file.
I just hate Quintus-style module system. I’m currently working on a large-ish project and parts of it are written in portable Prolog. And I absolutely don’t and will not use modules. Firstly GNU Prolog doesn’t support them, secondly they introduce more problems then they are solving.
What most programmers need is just predicate visibility (like static keyword in C) without stupid (:)/2 term. I have worked on term expansion and this term introduces too many unnecessary and otherwise avoidable inefficiencies and corner cases to consider so this alone makes it a harmful construct. Even if you don’t see : in your code it is silently added by most(?) Prolog engines.
Namespaces is an orthogonal idea to modules. Modules should not introduce new namespace into user program. And user should be able to decide it they want predicates acccessible in any namespace.
Name collision can be simply fixed by adding short mnemonic prefix to you predicates – it actually improves readability quite dramatically.
It leads to an always quantified style. In practice it happens
anyways, even if you have modules. Like http_THIS or http_THAT, as done in SWI-Prolog. It also shows that the
prefixing can be topical, not necessarely refering to a single
module, can also cross modules, and mixed prefixes can be used,
I am using like os_THIS, or cpu_THAT, etc…
Do I miss modules? Yes and no. A linter would be cool, for
enforcement to repeat Prolog text loads, just like people
repeat C .h file imports (*), so that Prolog texts become
separate self contained units, loading all they need.
But there are also patterns of dynamically loading Prolog texts,
and providing hooks. You find in old Prolog systems text
sources even the use of current_predicate/1 to see if a
hook is there or not. The modern way is probably to use
multifile/1 (**) and if there is no already existing hook, dynamic/1.
A linter could maybe also spot such problems resp solutions.
(*) Except if you create a master .h file which does all the
imports for you. But this runs counter to the idea that a
self contained unit, also means a mimimal import set.
(**) Some of these techniques are even not applicable to GNU Prolog.
Since GNU Prolog has only include/1 if am not mistaken, and
multifile/1 is a noop. Its more primitive than ISO core standard.
From what I understand Dogelog, GNU (and maybe some others) don’t have modules – and for a good reason. This points me to a question to language implementers: is it really that difficult to add predicate visibility without (:)/2? Because limited visibility is good to avoid name clashes, but from what I see it is always resolved using :.
The ISO core standard defines ensure_loaded/1. But
some module based Prolog systems, like Scryer Prolog
have for a while refused to implement it. Not sure what
the actual status is. Trealla Prolog might be more tollerant.
Basically a module system based Prolog might allow
module less coding for the user space. A Prolog text loaded
by ensure_loaded/1 need not have a module/1 directive
header. Module less coding in user space, might give the
end-user a handle for quick authoring of small scripts,
without the baggage of modules. Many Prolog playgrounds
offer this already when they show a split screen with some
Prolog text. Although they might create a “notebook” module
or something for you under the hood. But the idea would be
to have still file names, and multiple such Prolog texts just like
defined in the ISO core standard. In SWI-Prolog its quite a
headache, since a module less module, basically attaches to
a module “user” which is automatically imported everywhere.
So complexity is quite high, even when the request seems trivial.
The fun thing is that the Quintus module system was designed in the late 80s/early 90s with exactly that in mind: provide local predicates and have zero overhead. Just meta predicates that are exported from a module need a meta_predicate declaration to get the calling context right. foo:p(_) should have zero overhead. Using imported meta-predicates come with.a small overhead, but generally tiny compared to the meta call that is typically involved anyway.
For short, take.a non-module program. Add a module header listing all predicates that are called from other modules. Add meta_predicate declarations for all exported meta predicates and import the modules you need and you have a working program that is just as fast as what you started with.
The obvious gain: it is immediately clear what is public and what is private in a module and what modules depend on what other modules. Using a good editor that highlights the import/export status of predicates and calls completes the picture.
It still sounds too complex solution for a simple zero-cost visibility problem. I never implemented Prolog (but I tried to participate briefly) and I would’ve done this by name mangling.
So all “private” predicates have automatic prefix derived from the file names. And meta-predicates will still work because this prefix is known in the current file. So if you do let’s say maplist(small_pred_, MyList) then during compilation small_pred_ is replaced with myfile_small_pred_ and that’s all. No (:)/2 is needed!
My main source of frustration is having to deal with both G_0 and M:G_0 variables holding callable terms if I want to do anything advanced/generic. And those terms have very different structure, for example functor/3 will give unexpected results, etc.
In a module less prolog system, you indeed need to do nothing.
There are no (:)/2 terms that are passed as meta arguments, or
appear elsewhere for some reason.
So in a module less system you only have f(t1,..,tn) and functor/3
gives you f and n. In Prolog system with modules you might also
find a term of the form m:f(t1,..,tn). So people are using this
predicate as well, before calling functor/3 I guess, or after
calling functor/3, depending on the mode of your usage:
The library(reif) seems to have been written with a Prolog
system in mind, that has modules. The (:)/2 operator can
be added by a Prolog system to meta arguments so that
caller meta argument calls, know where to lookup predicates.
So in cases like for example such as below, you even don’t need to
program it via call/1 or any (:)/2, it stands without, because of
some peculiarities of the ISO core standard and how it defines (\+)/1,
and how the module standard simply extends the definition of
preparing a goal for execution (there is the quivalent of preparing
a clause for assertion in the ISO core standard):
forall(A, B) :-
   \+ (A, \+ B).
You don’t see that at runtime (:)/2 terms are passed around.
And calls to forall/2 are expanded by the current module context.
But then there are 1-2 more use cases where (:)/2 appears.
So the end-user is free to use (:)/2 for such calls in his code
as well, when he wants to specify a module in his code by either
a constant or a variable. There is a module standard which
P.S. But the module standard is relatively weak, it does not contain
programming utilities like strip_module/3. And also people, as
the library(reif) example shows, might not use strip_module/3.
The module standard has only these new and modified built-ins,
which is not 100% of the module story. And might even not completely
be followed by all Prolog systems that have modules:
That is roughly what XSB does for compound terms (f(…)). It comes with advantages and disadvantages. I find it a bit hard to judge which is overall better. The problem is that compound terms have two roles: they represent goals, but also data. XSB atoms are global, which implies they need a kludge for zero-arity predicates that are internally more like p() :- …
But, both approaches have pretty much zero runtime overhead and both requires some care when converting.a non-modular program to a modular one. For Quintus, these are exported meta predicates, for XSB that concerns data visibility and maybe zero-arity predicates. I might be wrong on the XSB details. XSB people are on this list, so please correct. The rationale behind Quintus is that exported meta-predicates are a quite advanced topic and users managing that are likely capable of dealing with the complexity.
If client code would use strip_module/3 consistently. It wouldn’t
matter how qualified calls are encoded. You can make it completely
opaque. But you might mostlikely still see (:)/2 in read term.
It might not be used in practice for Prolog systems and Prolog client
code, when the code wants to stay free of such low level helper tricks,
like leaking some optimization data structures into user space.
Bye
P.S.: You can also do such internalization of module less calls, for
speed up. Its very much the same principle like internalizing strings
for example. Only it might have a different goal than deduplication.
I use ir_site_new/2 to create internal representations of closures:
Regarding the XSB module system: A functor symbol always has a particular module associated with it. Code is associated with a functor symbol and, when predicate is called, the code associated with that symbol (in its module) is executed. There is zero overhead for invoking a predicate in a module; the exact same code address look-up is done.
How does a predicate symbol get its module? A Prolog source file may define a module (if the code includes an export declaration), in which case its predicate symbols are considered to be in that module. If a source file doesn’t define a module, then all its predicates are assumed to be in a standard “global” module, called “usermod”. Any code file can contain an :- import P/A from Mod. command, in which case then all uses of the predicate P/A will be assumed to have Mod as their associated module.
That is the basic XSB module system. Then (perhaps against my better judgment:-), we added a syntax for call of, e.g., Mod:p(…). If Mod is a constant, then this is compiled exactly the same as if you had declared p/n as imported from Mod. If Mod is a variable, then code is called to find the predicate symbol with the indicated name in the indicated module and call it. It this case, there is some overhead in the execution of the call. In all other cases, there is zero runtime overhead.
As Jan correctly noted, there are complexities/anomalies with 0-ary predicates, since in XSB atoms don’t have associated modules. Also, you can’t use moda:p(X) and modb:p(X) in the same module because that would lead to an attempt to import the same predicate from two different modules. (You can do it explicitly with :- import p/1 from modB as p_from_modB/1 and using p_from_modB(X), but I agree that might be awkward. And to be completely pedantic, executing the call to p_from_modB has an extra overhead of a single WAM jump instruction)
As Jan says, there are pros and cons to both XSB’s functor-based module system and Quintus’s predicate-based one. I’m partial to XSB’s, but maybe that’s not a surprise:-).
So the Wikipedia entry about XSB has an error, due to the 50 years
of Prolog paper having an error, wrongly attributing the topic
to the “XSB as an efficient Deductive Database Engine” paper:
If I interpret your explanations correctly atoms have a global scope.
But functors of arity > 0 have a local scope, and can be imported by
other modules. And you call it yourself a functor-based module
system, and not an atom-based module system. Calling it atom-based
seems to miss the mark, that functors are imported based on their arity.
In as far XSB has not introduced means like strip_module/3 in their
module system, but rather functor/4 to walk its data structures:
functor(?Term, ?Module, ?Functor, ?Arity)
The predicate functor/4 extends the functionality of functor/3 to
include the handling of modules. In XSB’s module system (See 3.4),
every structured term is in a module.
But XSB has also a declarations such as :- hilog closure which
then forces the functor to be an atom via an apply/n wrapper. I guess
taking advantage of the then global scope for higher order calling.
So the maplist/2 example I gave would work out a little differently.
Although XSB might even not have maplist/2 at all, these are things
that entered Prolog systems from functional programming recently.
Yes, there is that confusion with notion of “atom”. That term has a checkered history in logic. I think it is better described as a “term” based module system. My impression is that the phrase “atom-based” as applied to a module system started with BIM-Prolog. Gemini seems to agree, responding to my question about the kind of module system BIM had with “BIM-Prolog utilized an atom-based module system rather than a predicate-based one.” Anyway…
I’m not sure what strip_module does, but it sounds like it makes the predicate not be in a module. That’s not possible in XSB; every functor symbol has a module. You could change it to usermod, if you wished, but you’re stuck with some module. And, yes, meta-programming is different in the different module frameworks. I find it usually more convenient with the XSB module system, but again that is a matter of taste and familiarity.
Hilog, in XSB, is very different beast. When that syntax was added to XSB, it was NOT integrated with the module system, at least not very well. And that was a serious mistake. For it to be more useful, it should be changed to integrate batter. I, personally, am not convinced it is really worth the effort and incompatibilities at this point, but I could be convinced.
It is a SWI-Prolog addition. It takes a term, embedded in zero or more Module:RealTerm and gives you the innermost module (the most deeply nested Module:RealTerm or the current context module) and the plain term. It is not used a lot, especially since a predicate that defines an argument as a meta-argument is guaranteed to receive a plain Module:RealTerm term, i.e., the :/2 term is always there and it is never nested.
Well lean and mean is totally en vogue. Artificial Intelligence (AI)
companies currently making mathematicians obsolete by fleshing out,
in increasing frequency, Microsoft Lean theorem prover based
certificates, for so far unresolved conjectures.
So the ISO core standard has just bypassed, spending 10
years in a philosophy faculty and marvelling how homoiconicity
could be modelled inside set theory and FOL, by making
call/n part of the aforementioned standard:
8.15.4 call/2..8
These built-in predicates provide support for higher-order programming.
a) Let call(p(X1,...,XM), Y2, ..., YN) be the goal to be executed, M ≥ 0,
b) Execute call(p(X1, ..., XM, Y2, ..., YN)) instead. https://www.complang.tuwien.ac.at/ulrich/iso-prolog/dtc2#call
I used call/2 in the maplist example. But more strikingly are
examples where higher-order logic programming gives alternative
solutions to object orientation and/or parameterized modules.
Take this example from SICStus Prolog:
Using higher order and the core only, is a little clumsy,
it requires more argument passing, but an implementation
of call/n as a built-in is trivial and doesn’t require any new
syntax operators. It gives the same results:
The result is obtained with smaller footprint in Prolog system
size and complexity. So while object orientation and/or parameterized
modules seem to be disposable. Higher-order logic programming
with call/n gives an almost indisposable spin to homoiconicity.
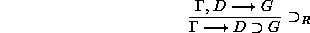
Not really. Its based on embedded implication, which is
a different mechanism. It is this inference rule which is not
in the ISO core standard, and cannot easily be added
by a built-in like call/n. The inference rule is supposition:
One might try to hide the details when and how supposition
is invoked when you use your modules. But concerning
the footprint in Prolog system size and complexity, you
have to consider the trade off between supposition based
translations and a tiny call/n built-in predicate. With supposition
the query would be basically as below. So you don’t have an
additional parameter, but you posit dynamically and temporarily
a program, supposition is the mechanism for reuse:
And (=>)/2 might be slow, if your supposition tries to provide large
Prolog terms in a term sharing manner, it might copy them! So
your embedded implication would need to solve a lot of issues.
On the other hand a predicate call/n usually automatically plays
well with the structure sharing of modern Prolog systems.
Bye
P.S.: A little slower than a built-in call/n is this bootstrapping:
call(C, X) :-
    ...

call(C, X, Y) :-
    C =.. [F|L],
    append(L, [X,Y], R),
    D =.. [F|R],
    call(D).

call(C, X, Y, Z) :-
    ...
If you have a module system as well some new challenges might enter,
since atoms, the F, are now polymorphic in arity. So there is an additional
semantic complication involved, besides juggling with strip_module/3.